Local-model users pick their engine on Reddit. Magnitude isn’t in the threads.
r/LocalLLaMA gets 845K visitors a week and argues about inference engines daily. Strata reached 31.1K GitHub stars a month after launch, and oMLX has 23K and its own subreddit. Magnitude has 7.3K. Its one r/LocalLLaMA thread is a repost from Hacker News day, and the questions in its 23 comments never got an answer from the team.
What’s worked so far. Tom’s posts on X and a #1 on Hacker News. Reddit has only seen reposts.
Views on Tom’s top posts on X, from an account with 3,823 followers
Hacker News
#1on Sep 30, with “up to 2x faster than llama.cpp”.GitHub Trending
Sep 3“Magnitude is on GitHub Trending!!”The posts that travel on X are what r/LocalLLaMA upvotes: which models a machine can run, tok/s on a named box, a Mac Studio against DGX Sparks. 4,295 people bookmarked the model-catalog post. Each of these can go to Reddit as a post written for that subreddit.
The engines Reddit talks about. Strata went from zero to 31.1K stars in a month.
GitHub stars, and each engine’s best-known Reddit thread
The threads. 17 since September where people pick an engine, 1,010 comments, no Magnitude.
Your one r/LocalLLaMA thread
r/LocalLLaMA · Sep 30 · reposted by u/paranoidray with the HN link Open source inference engine (like LM Studio or Unsloth Desktop) that optimizes itself for your exact hardwareSince then Magnitude has shipped an Arch package and a full benchmark page that lists where it’s slower. The thread doesn’t know, and it’s still open.
Questions still waiting there
Picking an engine right now
Beginners asking where to start, Ollama users asking what’s faster, new DGX Spark and Mac Studio owners asking what to run. The answers they get: llama.cpp, vLLM, LM Studio, MLX, Strata. Magnitude has numbers for most of these machines on its benchmark page.
comments across these 17 threads, and none mention Magnitude. Each one can still take a reply.
Where they are
Search. Google sends “ollama alternative” to Reddit. Reddit is #1 on 15 of these.
| Search | Google position 1–10 | Top ranking Reddit thread | Magnitude |
|---|---|---|---|
| Leaving Ollama7 | |||
| ollama alternative | 1 | r/localaiapps · May 2026Best Ollama alternatives if you want local AI without living in the terminal | absent |
| faster than ollama | 2 | r/LocalLLaMA · Jan 2026llama.cpp vs Ollama: ~70% higher code generation… | absent |
| ollama vs llama.cpp | 1 | r/LocalLLaMA · Jul 2025Help choosing between Ollama, llama.cpp, or something… | absent |
| lm studio vs ollama | 2 | r/LocalLLaMA · Jan 2025Why do people like Ollama more than LM Studio? | absent |
| lm studio alternative | 1 | r/LocalLLaMA · Oct 2025Good alternatives to Lmstudio? | absent |
| ollama slow | 1 | r/ollama · Apr 2026Is Ollama actually slow or am I missing something? | absent |
| ollama speculative decoding | 1 | r/ollama · Nov 2025Speculative decoding: faster inference for local LLMs over the network? | absent |
| The fastest engine8 | |||
| fastest local llm inference | 1 | r/LocalLLaMA · Apr 2024What’s the fastest local inference engine right now? | absent |
| best inference engine for mac | 1 | r/LocalLLaMA · Apr 2025Fastest inference on Mac: MLX, llama.cpp, vLLM, exLlamav2, sglang? | absent |
| open source inference engine | 1 | r/LocalLLaMA · Oct 2026Deepseek released DeepInfer – open source high-performance inference framework | absent |
| how to run llm locally | 1 | r/LocalLLaMA · May 2025Running LLMs locally – tips & recommendations? | absent |
| mlx vs llama.cpp | 1 | r/LocalLLaMA · Mar 2026MLX is not faster. I benchmarked MLX vs llama.cpp on M1… | absent |
| mlx vs ollama | 1 | r/LocalLLM · Mar 2026Local LLM benchmark: MLX-LM vs. Ollama | absent |
| vllm vs ollama | 2 | r/LocalLLaMA · Oct 2024Ollama or vLLM for serving | absent |
| vllm vs llama.cpp | 2 | r/LocalLLaMA · Jan 2026Llama.cpp vs vLLM | absent |
| Which model, which machine8 | |||
| best local llm mac | 1 | r/LocalLLM · Mar 2026What’s the best local LLM for Mac? | absent |
| run llm locally mac | 2 | r/LocalLLM · Apr 2026Beginners guide for Mac? | absent |
| best way to run qwen locally | 1 | r/LocalLLaMA · Jul 2026I made a very detailed guide on how to run Qwen 27B… | absent |
| run gemma 4 locally | 2 | r/LocalLLaMA · Apr 2026What is the current solution to running Gemma 4 locally? | absent |
| what llm can i run | 5 | r/LocalLLM · Mar 2026How do I know what LLMs I am capable of running locally? | absent |
| local ai app mac | 5 | r/MacOS · Jul 2026Your Mac. Your AI. Free. I built an open source native app that runs AI models… | absent |
| strix halo llm | 1 | r/StrixHalo · Jun 2026A buyer’s guide to local LLM hardware after running a Strix Halo box for 6 months | absent |
| dgx spark llm | 3 | r/LocalLLM · Jun 2026My experiences with the DGX Spark so far as an LLM newbie… | absent |
| Local models in your agent5 | |||
| local llm for coding | 1 | r/LocalLLaMA · Mar 2026Best local LLM for coding | absent |
| claude code local model | 3 | r/LocalLLaMA · Jul 2025Use Claude Code with local models | absent |
| codex local model | 2 | r/LocalLLM · Apr 2026Does something like OpenAI’s “codex” exist for local models? | absent |
| hermes agent local model | 2 | r/hermesagent · Jul 2026Which local model gives the best experience with Hermes Agent… | absent |
| opencode local model | 4 | r/LocalLLaMA · Aug 2025Best local models to run OpenCode? | absent |
Google’s AI Overviews on 7 “which engine” searches from the table
The Overview for ollama alternative lists LM Studio, Jan, Msty, Atomic Chat, vLLM, llama.cpp, AnythingLLM and LocalAI.
“…Apple Silicon users achieve top speeds using MLX-based frameworks or specialized runtimes like Splash and Magnitude.”
Sources: the 2024 r/LocalLLaMA thread that ranks #1, and one other site. Reddit threads are what these answers draw on. A current one that names Magnitude gives the next answer something to cite.Subreddits. Where local-model users are, by visitors a week.
magnitude server setup belongs here.Promoted apps must be production ready, with docs.r/BestGitHubRepos (195K a week) already reposted Magnitude on its own: 197 upvotes. Its rules welcome a maintainer sharing a repo, as long as they say so.
What we’d do. Take what works on X to the subreddits where engines get picked. All of it run by us.
What you do
Nothing, week to week.
Once, at the start: say yes to the founder account, a new one in Tom’s name or his existing one. That’s it.
Want to see founder posts before they go up? Say so and we’ll send them first. It’s optional.
What we do
- Pick the threads, subreddits and searches every week
- Write every post and reply, in the persona’s voice and in Tom’s
- Post from both accounts, and answer the comments that come back
- Run the numbers on our own Mac with your open-source benchmark harness
- Write only from what you’ve already published: README, docs, benchmark page, releases, Tom’s X posts
- Replace any post moderators remove
- Track stars, downloads and threads, and send you a short report each month
Posts as Tom, written and posted by usFounder account
- Answer every question in the Sep 30 threadwhat the tuning changes · Arch now has a package · multi-GPU status · where it’s slower, from your own benchmark page
- Magnitude vs Ollama on an M4 Pro and a DGX Spark: 11 models, with the harness commandr/LocalLLaMA, disclosed as the team · the slower cases included
- Mac Studio vs 4× DGX Spark vs 4× Ryzen AI Halo124K views on X · r/LocalLLaMA, r/StrixHalo, r/DGX_Spark
- Which models can your machine run?297K views on X · r/LocalLLM, r/ollama, r/macmini
- A release post for each version, the way Lemonade does itr/LocalLLaMA · changelog, numbers, what’s next
Live threads to answer nowPersona account, two from Tom
- r/LocalLLaMA: Why AnythingLLM is moving from Ollama to Lemonade and llama.cpp2.2x Ollama’s decode, same OpenAI-compatible API · 53 comments
- r/LocalLLaMA: Got 2x DGX Sparks. Excited and confused!from the founder account: Tom runs Hermes on a Spark · Qwen 3.6 35B: 85.8 tok/s on Ollama, 216 on Magnitude · 194 comments
- r/hermesagent: Cheapest decent machine for Hermes Agent with local models?tok/s for every model before you download, one-click Hermes
- r/LocalLLM: MacBook Pro M5 Pro 48GB, Qwen 27B with Ollama is extremely slowQwen 3.8 27B on an M4 Pro: 21.0 tok/s on Ollama, 34.3 on Magnitude
- r/ollama: How on gods green earth do i start this?Discover picks a model that fits the machine · 91 comments
- r/LocalLLaMA: Best current R9700 inference engine?from the founder account · AMD GPUs supported
- r/MacStudio: can you run qwen3.8-27b for us?run it and post the numbers
New posts written to rankPersona account
- Ollama alternatives with numbers: speed on a Mac and an NVIDIA boxollama alternative #1, a 5-month-old list without Magnitude · faster than ollama #2
- Why Ollama is slow on a Mac, and what to changeollama slow #1 · ollama speculative decoding #1
- The fastest local inference engine on a Mac right nowfastest local llm inference #1, a 2024 thread · best inference engine for mac #1
- Local models in Claude Code, Codex, Hermes and OpenCodeclaude code local model #3 · hermes agent local model #2 · opencode local model #4
- Each names Magnitude as part of the answer, with no link
House rules
The baseline we re-measure every month
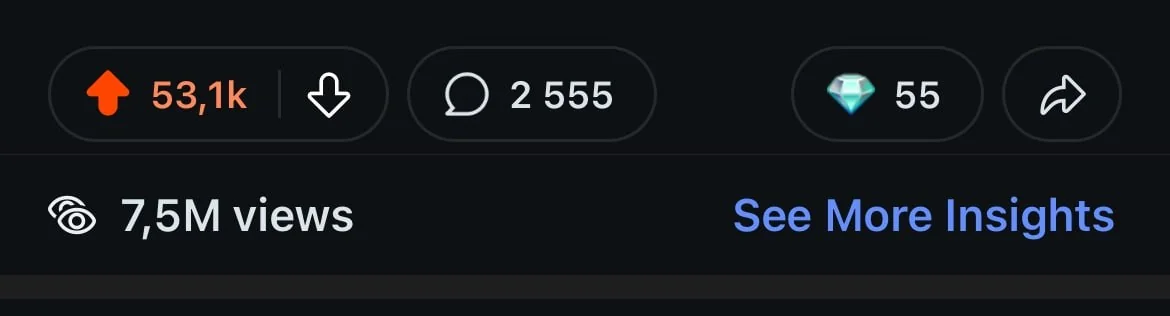
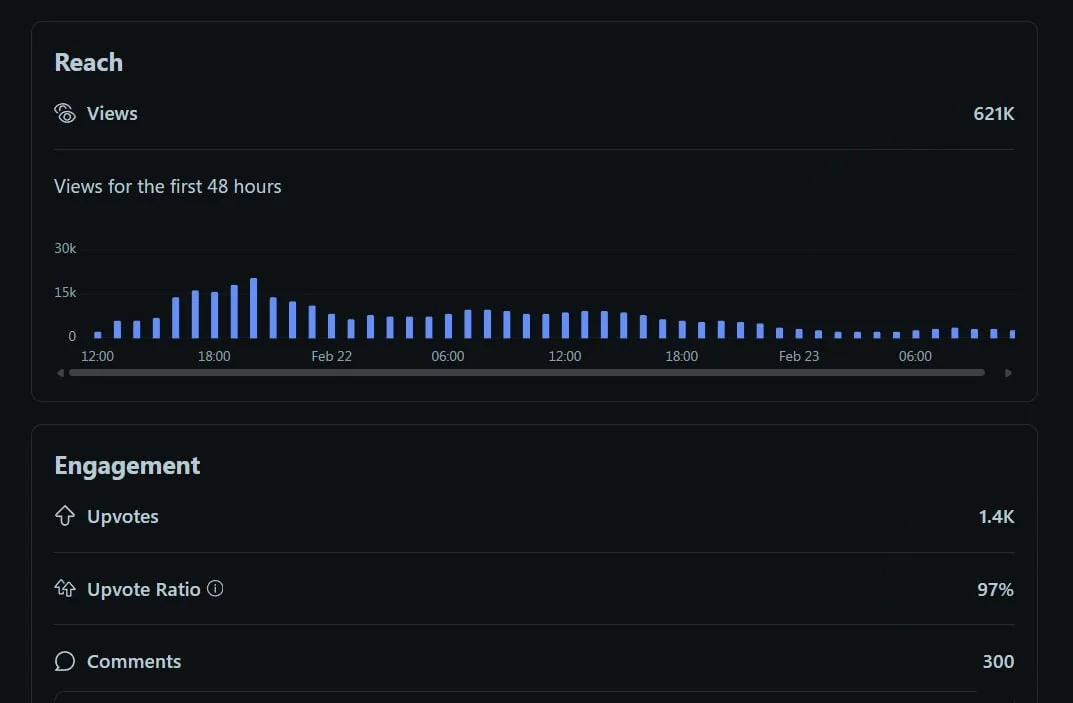
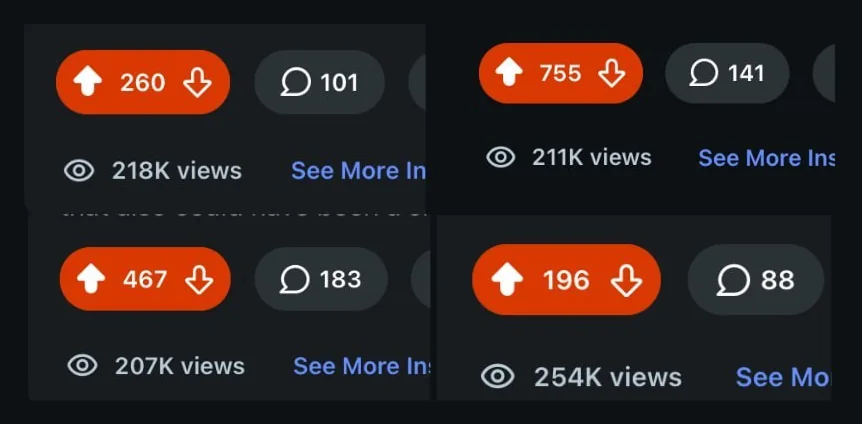
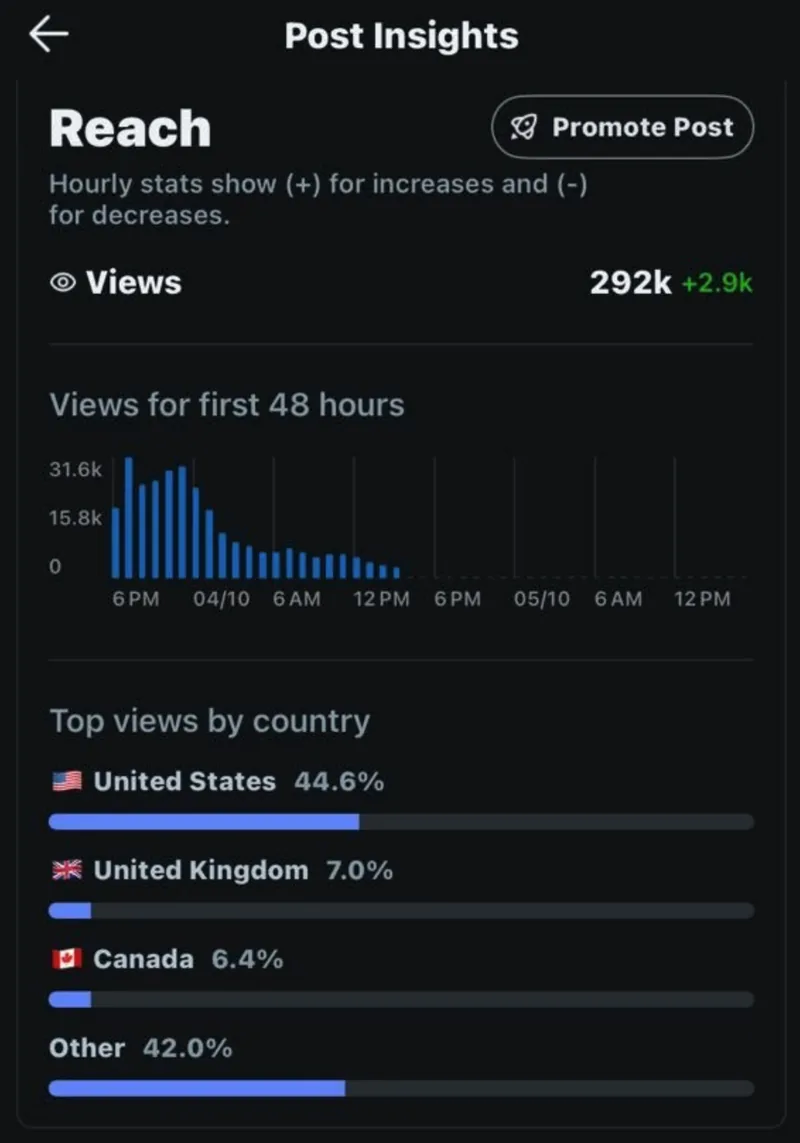
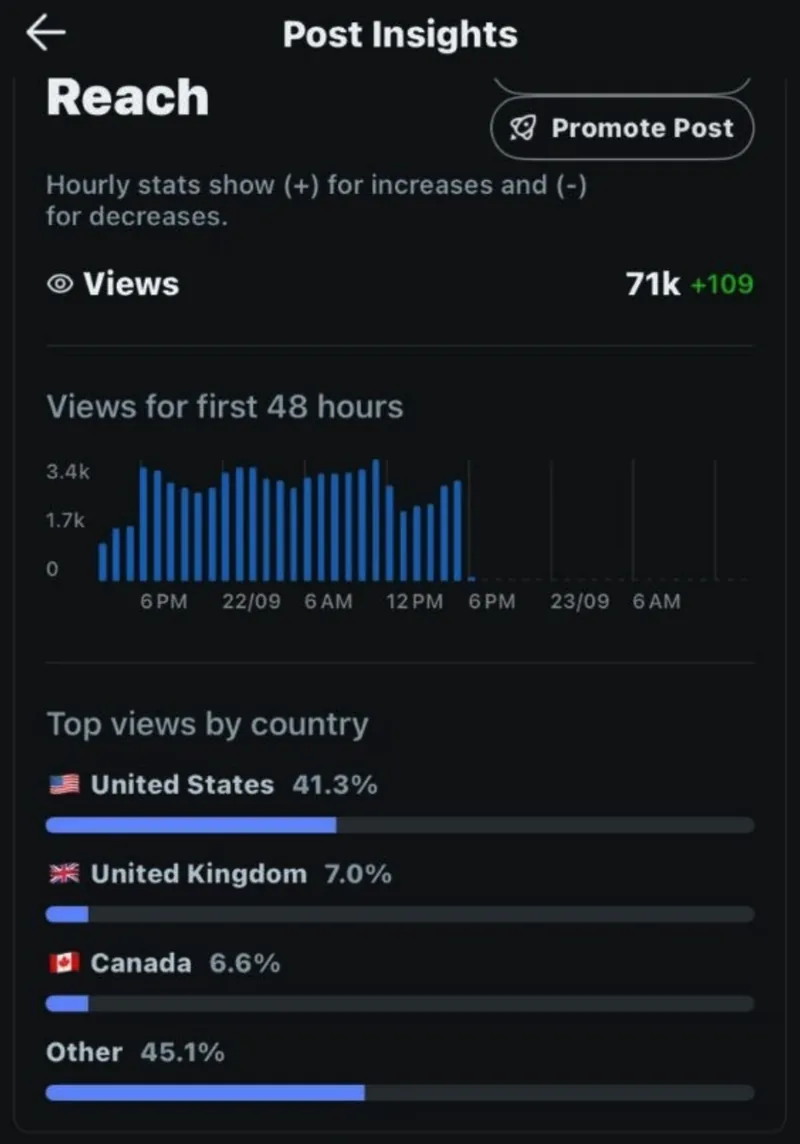
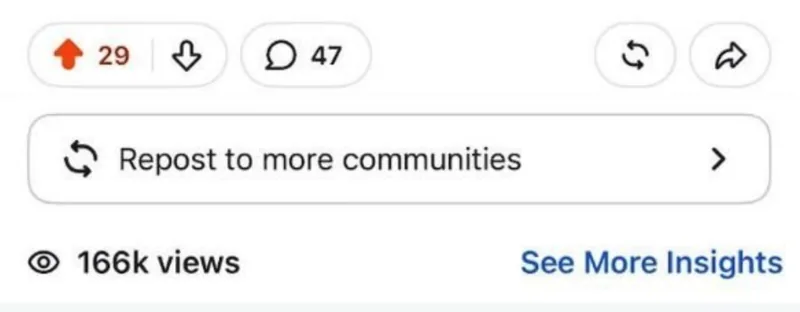
Proof. Our posts get seen: 9.5M views across 9 posts.
Accounts. A persona, the founder, or both. Month to month, and we run both.
A Mac developer running coding agents on local models
Runs Hermes and OpenCode on local models on a MacBook Pro, posts tok/s from their own machine, and answers “what should I run” questions. Magnitude is one of the tools they use and compare.
- Mac owners ask the most: 4 of the 17 live threads and 6 of the 28 searches are about Macs.
- Magnitude’s Mac numbers are its strongest: 2.19x Ollama’s decode on an M4 Pro.
- Agent users are who Magnitude connects to in one click: r/ClaudeCode (988K a week), r/hermesagent (142K), r/opencode (137K).
month to month
- Posts
- About 20 answers in engine, Mac and agent threads, and 10 new posts written to rank
- Where
- r/LocalLLaMA, r/LocalLLM, r/ollama, r/macmini, r/MacStudio, r/hermesagent, r/opencode, r/ClaudeCode
Tom, posting as the builder
We write and post as Tom, openly as the builder: benchmarks, releases, hardware comparisons and straight answers to engine questions. Tom doesn’t write, post or reply.
- r/LocalLLaMA asks makers to disclose, and builders who do well there post as builders: AMD’s Lemonade engineer (260 and 182 upvotes), Gufo’s builders (262), Basalt’s developer.
- Tom’s X posts already work this way: 398K, 297K and 124K views.
- The Sep 30 thread has 5 open questions only the team can answer.
month to month
- Posts
- About 3 posts about Magnitude and 27 answers on engines, models and hardware. Under 1 in 10, as r/LocalLLaMA asks
- Where
- r/LocalLLaMA, r/LocalLLM, r/DGX_Spark, r/StrixHalo, r/selfhosted, r/BestGitHubRepos
Some posts get removed. Out of 30, around 5 can be. Each removed post is replaced with a new one, so every account still delivers its full count for the month.
Price